By using this site, you agree to the Privacy Policy and Terms of Use.
Accept
AIModelKitAIModelKitAIModelKit
  • Home
  • News
    NewsShow More
    SpaceXAI’s Grok Tool Uploading Users’ Entire Codebase to Cloud Storage: What You Need to Know
    SpaceXAI’s Grok Tool Uploading Users’ Entire Codebase to Cloud Storage: What You Need to Know
    4 Min Read
    New York Leads the Way: First State to Enforce One-Year Moratorium on New AI Data Centers
    New York Leads the Way: First State to Enforce One-Year Moratorium on New AI Data Centers
    4 Min Read
    AI Replacing New York Nurses: Why Patients Should be Concerned About Quality of Care
    AI Replacing New York Nurses: Why Patients Should be Concerned About Quality of Care
    5 Min Read
    Navigating AI Agent Crawlers and Cloudflare’s New Rules: A Comprehensive Guide
    Navigating AI Agent Crawlers and Cloudflare’s New Rules: A Comprehensive Guide
    5 Min Read
    How Apple’s Self-Driving Car Program Paved the Way for Advanced AI Chip Technology
    How Apple’s Self-Driving Car Program Paved the Way for Advanced AI Chip Technology
    4 Min Read
  • Open-Source Models
    Open-Source ModelsShow More
    HiRO-ACEv2: Cost-Effective Simulation of Extreme Weather at 3 km Resolution
    HiRO-ACEv2: Cost-Effective Simulation of Extreme Weather at 3 km Resolution
    5 Min Read
    Unlocking Efficient Autoregressive Video Generation with SemanTok: Predictable Semantic Tokens by Stability AI
    Unlocking Efficient Autoregressive Video Generation with SemanTok: Predictable Semantic Tokens by Stability AI
    5 Min Read
    4Director: Mastering Video World Models with Rigid 3D Geometry | Stability AI Insights
    4Director: Mastering Video World Models with Rigid 3D Geometry | Stability AI Insights
    6 Min Read
    Leveraging Earth AI’s Geospatial Foundation Models to Enhance Global Public Health Initiatives
    Leveraging Earth AI’s Geospatial Foundation Models to Enhance Global Public Health Initiatives
    5 Min Read
    Enhancing AI Image Generation with Diffusion Controller: A Simplified Unified Approach
    Enhancing AI Image Generation with Diffusion Controller: A Simplified Unified Approach
    5 Min Read
  • Guides
    GuidesShow More
    Your Comprehensive Guide to Practical Constraint Decoding: Basics and Applications
    Your Comprehensive Guide to Practical Constraint Decoding: Basics and Applications
    6 Min Read
    KDnuggets Weekly Data Science News Roundup: Highlights from July 20, 2026
    KDnuggets Weekly Data Science News Roundup: Highlights from July 20, 2026
    4 Min Read
    Unlock Your AI Potential with Kaggle and Google’s Free 5-Day Agentic AI Course
    Unlock Your AI Potential with Kaggle and Google’s Free 5-Day Agentic AI Course
    6 Min Read
    Top 5 High-Performance MCP Servers for Optimal Agentic Development
    Top 5 High-Performance MCP Servers for Optimal Agentic Development
    6 Min Read
    Top 5 Free Resources for Understanding Agentic AI: Unlock Your Knowledge
    Top 5 Free Resources for Understanding Agentic AI: Unlock Your Knowledge
    6 Min Read
  • Tools
    ToolsShow More
    Granite Switch 4.1: Unified Chat, Decision-Making, and Voice Features from a Single Endpoint
    Granite Switch 4.1: Unified Chat, Decision-Making, and Voice Features from a Single Endpoint
    5 Min Read
    Create Local AI Applications Using C++ and NVIDIA TensorRT RTX Samples
    Create Local AI Applications Using C++ and NVIDIA TensorRT RTX Samples
    5 Min Read
    Unlock Near-Astra Intelligence in Your Daily Work with GPT-6.1 Sol on Amazon Bedrock
    Unlock Near-Astra Intelligence in Your Daily Work with GPT-6.1 Sol on Amazon Bedrock
    6 Min Read
    Reproducible Benchmark Results: How UK AISI and EvalEval Are Leading the Way
    Reproducible Benchmark Results: How UK AISI and EvalEval Are Leading the Way
    6 Min Read
    Hugging Face Welcomes Jun Kim, oMLX Creator and Maintainer, to Boost the MLX Community
    Hugging Face Welcomes Jun Kim, oMLX Creator and Maintainer, to Boost the MLX Community
    4 Min Read
  • Events
    EventsShow More
    How European Cities Use NVIDIA-Powered AI Agents for Enhanced Urban Operations
    How European Cities Use NVIDIA-Powered AI Agents for Enhanced Urban Operations
    5 Min Read
    Boosting Everyday Courage in Educational Leaders: A Guide to Choosing Confidence
    Boosting Everyday Courage in Educational Leaders: A Guide to Choosing Confidence
    5 Min Read
    Boosting OpenAI’s GPT-6 Astra Performance: The Role of NVIDIA GPUs in Accelerating AI Technology
    Boosting OpenAI’s GPT-6 Astra Performance: The Role of NVIDIA GPUs in Accelerating AI Technology
    4 Min Read
    Jensen Huang at Dreamforce: ‘Now We Can Know Everything and Achieve Anything’
    Jensen Huang at Dreamforce: ‘Now We Can Know Everything and Achieve Anything’
    5 Min Read
    Essential Strategies for Preparing Students for a Career in Quantum Computing
    Essential Strategies for Preparing Students for a Career in Quantum Computing
    5 Min Read
  • Ethics
    EthicsShow More
    Are Teachers More Like Coaches or Pastors? Explore the Differences Based on Your Location
    Are Teachers More Like Coaches or Pastors? Explore the Differences Based on Your Location
    4 Min Read
    How AI Labs are Acquiring Data from Defunct Startups to Enhance Model Training
    How AI Labs are Acquiring Data from Defunct Startups to Enhance Model Training
    6 Min Read
    UK Enhances Cyber Defenses: Minister Urges AI Firms to Boost Safety Measures
    UK Enhances Cyber Defenses: Minister Urges AI Firms to Boost Safety Measures
    6 Min Read
    Understanding the Side Effects of GLP-1 Weight Loss Drugs: What You Need to Know
    Understanding the Side Effects of GLP-1 Weight Loss Drugs: What You Need to Know
    5 Min Read
    Understanding Withholding Delay: A Welfare Model for Open-Weight AI Releases in Asymmetric Proliferation
    Understanding Withholding Delay: A Welfare Model for Open-Weight AI Releases in Asymmetric Proliferation
    6 Min Read
  • Comparisons
    ComparisonsShow More
    InternBootcamp: Enhancing LLM Reasoning Through Verifiable Task Scaling Techniques
    InternBootcamp: Enhancing LLM Reasoning Through Verifiable Task Scaling Techniques
    4 Min Read
    Enhancing Anomaly Detection in Collider Experiments through Contrastive Learning for Better Interpretability
    Enhancing Anomaly Detection in Collider Experiments through Contrastive Learning for Better Interpretability
    6 Min Read
    Exploring the Impact of Quantization on Self-Explanations in Large Language Models: Can LLMs Explain Themselves?
    Exploring the Impact of Quantization on Self-Explanations in Large Language Models: Can LLMs Explain Themselves?
    5 Min Read
    CytoNet: A Foundation Model for Understanding the Human Cerebral Cortex at Cellular Resolution
    CytoNet: A Foundation Model for Understanding the Human Cerebral Cortex at Cellular Resolution
    5 Min Read
    Optimizing Nonconvex-Nonconcave Min-Max Problems with a Limited Maximization Domain: Insights from [2110.03950]
    Optimizing Nonconvex-Nonconcave Min-Max Problems with a Limited Maximization Domain: Insights from [2110.03950]
    5 Min Read
Search
  • Privacy Policy
  • Terms of Service
  • Contact Us
  • FAQ / Help Center
  • Advertise With Us
  • Latest News
  • Model Comparisons
  • Tutorials & Guides
  • Open-Source Tools
  • Community Events
© 2025 AI Model Kit. All Rights Reserved.
Reading: Boosting AI Innovation: How PyTorch is Revolutionizing Performance with Intelligent Caching
Share
Notification Show More
Font ResizerAa
AIModelKitAIModelKit
Font ResizerAa
  • 🏠
  • 🚀
  • 📰
  • 💡
  • 📚
  • ⭐
Search
  • Home
  • News
  • Models
  • Guides
  • Tools
  • Ethics
  • Events
  • Comparisons
Follow US
  • Latest News
  • Model Comparisons
  • Tutorials & Guides
  • Open-Source Tools
  • Community Events
© 2025 AI Model Kit. All Rights Reserved.
AIModelKit > Tools > Boosting AI Innovation: How PyTorch is Revolutionizing Performance with Intelligent Caching
Tools

Boosting AI Innovation: How PyTorch is Revolutionizing Performance with Intelligent Caching

aimodelkit
Last updated: October 30, 2025 6:32 pm
aimodelkit
Share
Boosting AI Innovation: How PyTorch is Revolutionizing Performance with Intelligent Caching
SHARE

LMCache: Transforming Large Language Model Inference in the PyTorch Ecosystem

We’re thrilled to announce that LMCache has officially joined the PyTorch Ecosystem. This exciting addition enhances the open-source toolkit designed for advancing AI inference. For those interested in exploring the diverse PyTorch projects, the PyTorch Landscape showcases these innovative tools and details how projects can become part of this vibrant ecosystem.

Contents
  • Understanding the Challenges of Large Language Models
  • What is LMCache?
  • How LMCache Enhances LLM Performance
  • Key Features of LMCache
  • The Architecture of LMCache
  • Performance Metrics
  • Rapid Adoption and Community Growth
  • Getting Started with LMCache
  • Learn More About LMCache

Understanding the Challenges of Large Language Models

Running inference for large language models (LLMs) presents unique challenges. While inference requires fewer resources than training, escalating costs can become a pressing issue, especially as demand for quick response times and precise outputs increases. In projects where accuracy is paramount, finding efficient ways to manage resources without sacrificing performance becomes essential.

What is LMCache?

Developed following groundbreaking research from a team at the University of Chicago, LMCache rises to the occasion as a revolutionary Key-Value caching (KV caching) solution. This software extracts and stores kv caches generated by modern LLM engines like vLLM and SGLang, allowing for the sharing of these caches across various engines and queries.

How LMCache Enhances LLM Performance

LMCache offers a transformative interface for LLM engines by shifting from a model that processes individual tokens toward one that leverages KV caches as a robust storage and communication medium. Its architecture supports both cache offloading and prefill–decode (PD) disaggregation, allowing for more efficient cross-engine cache transfers.

Key Features of LMCache

The exceptional performance of LMCache can be attributed to several key features:

More Read

Comprehensive Dataset for Document Visual Question Answering: Enhance Your AI Models
Evaluating LLM Performance on AI-Generated CUDA Code Using ComputeEval 2025.2: A Comprehensive Benchmarking Study
July 2026 Security Incident Disclosure: Key Insights and Updates
NVIDIA cuQuantum Enhances Simulation Speed with Dynamic Gradients and DMRG Features
Apply Now: Student Ambassador Program Accepting Applications!
  1. Optimized KV Cache Data Movement:
    LMCache incorporates performance enhancements, including batched data movement operations and compute and I/O pipelining, significantly improving overall efficiency.

  2. Modular KV Cache Connector Component:
    This feature allows LMCache to evolve rapidly alongside inference engines, providing flexibility in implementation.

  3. First-Class Control API:
    With capabilities such as pinning, lookup, cleanup, movement, and compression, the control API enables dynamic orchestration of caches across GPU, CPU, storage, and network layers.

The Architecture of LMCache

LMCache strategically positions itself between LLM inference engines and storage backends. This architecture is designed to streamline data flows, ensuring that caching occurs seamlessly without compromising speed or accuracy.
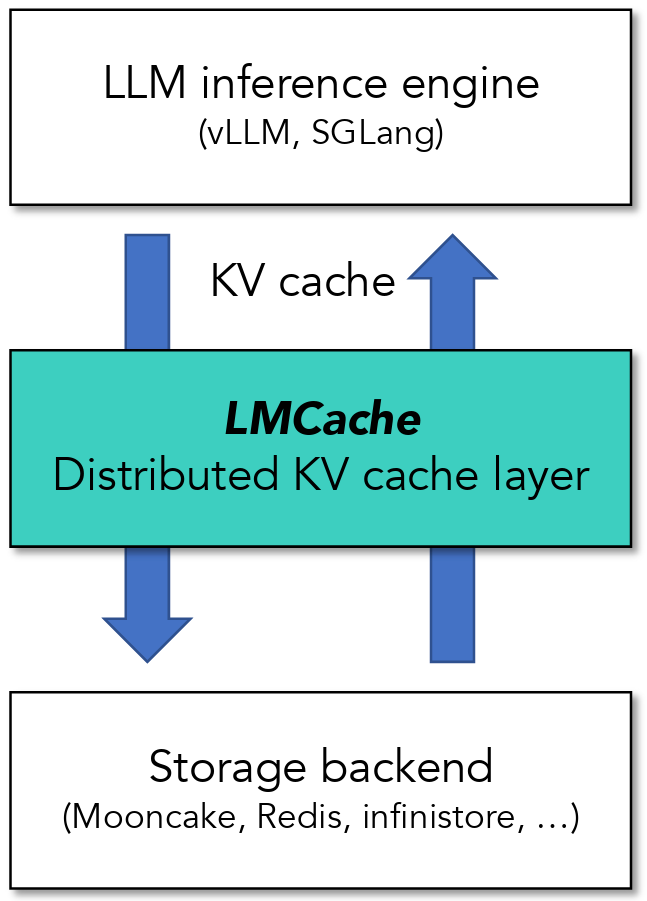
LMCache Architecture
LMCache sits between LLM Inference Engines and storage backends.

Performance Metrics

Recent evaluations demonstrate that when combined with vLLM, LMCache achieves exceptional throughput improvements—up to 15 times in scenarios such as multi-round question answering, which is crucial for applications like chatbots, and for document analysis, including Retrieval-Augmented Generation (RAG). This level of efficiency positions LMCache as a vital tool for enterprises looking to optimize inference systems.

Rapid Adoption and Community Growth

The adoption of LMCache is swiftly gaining traction among enterprise systems, offering invaluable insights for future KV caching solutions. The source code is openly available on GitHub: LMCache GitHub Repository. This move fosters an engaged community willing to contribute and enhance the capabilities of LMCache further.

Getting Started with LMCache

If you’re utilizing vLLM as your preferred serving engine, setting up LMCache is straightforward. Use the following command to install:

bash
pip install lmcache vllm

vllm serve Qwen/Qwen3-4B-Instruct-2507
–kv-transfer-config ‘{
// Your configuration here
"kv_connector":"LMCacheConnectorV1", "kv_role":"kv_both"}’

With this simple setup, your LMCache-augmented vLLM server will be up and running, ready to enhance your LLM’s performance.

Learn More About LMCache

For those eager to dive deeper into LMCache, a wealth of resources is available for exploration. Whether you’re an enterprise user or a developer interested in the intricacies of KV caching, LMCache brings an array of functionalities tailored to meet diverse needs.

If you have questions or seek further discussion, we encourage you to join the conversation on LMCache’s Slack community. We’re excited to hear from you and explore how LMCache can elevate your AI projects!

Inspired by: Source

Mastering Data Filtering: Overcoming Common Challenges in Data Management
Feedback on the U.S. National AI Research Resource Interim Report: Key Insights and Recommendations
Unlocking the Power of Pull Requests and Discussions: A Comprehensive Guide 🥳
NVIDIA cuPyNumeric 25.03: Fully Open Source Release with PIP and HDF5 Support
Driving Change: CO2 Emissions Reduction and the 🤗 Hub’s Leadership Role

Sign Up For Daily Newsletter

Get AI news first! Join our newsletter for fresh updates on open-source models.

By signing up, you agree to our Terms of Use and acknowledge the data practices in our Privacy Policy. You may unsubscribe at any time.
Share This Article
Facebook Copy Link Print
Previous Article Thompson Sampling in Function Spaces: Leveraging Neural Operators for Enhanced Performance Thompson Sampling in Function Spaces: Leveraging Neural Operators for Enhanced Performance
Next Article Bending Spoons Acquires AOL: Uncovering the Value of Legacy Platforms Bending Spoons Acquires AOL: Uncovering the Value of Legacy Platforms

Stay Connected

XFollow
PinterestPin
TelegramFollow
LinkedInFollow

							banner							
							banner
Explore Top AI Tools Instantly
Discover, compare, and choose the best AI tools in one place. Easy search, real-time updates, and expert-picked solutions.
Browse AI Tools

Latest News

Granite Switch 4.1: Unified Chat, Decision-Making, and Voice Features from a Single Endpoint
Tools
Are Teachers More Like Coaches or Pastors? Explore the Differences Based on Your Location
Ethics
HiRO-ACEv2: Cost-Effective Simulation of Extreme Weather at 3 km Resolution
Open-Source Models
How European Cities Use NVIDIA-Powered AI Agents for Enhanced Urban Operations
Events
//

Leading global tech insights for 20M+ innovators

Quick Link

  • Latest News
  • Model Comparisons
  • Tutorials & Guides
  • Open-Source Tools
  • Community Events

Support

  • Privacy Policy
  • Terms of Service
  • Contact Us
  • FAQ / Help Center
  • Advertise With Us

Sign Up for Our Newsletter

Get AI news first! Join our newsletter for fresh updates on open-source models.

AIModelKitAIModelKit
Follow US
© 2025 AI Model Kit. All Rights Reserved.
Welcome Back!

Sign in to your account

Username or Email Address
Password

Lost your password?